


On November 5, Runway explained how it optimized Characters to generate video during a conversation. The post accompanies a preprint submitted on November 3 and describes improvements to an existing service. [1]
How it sustains 24 fps
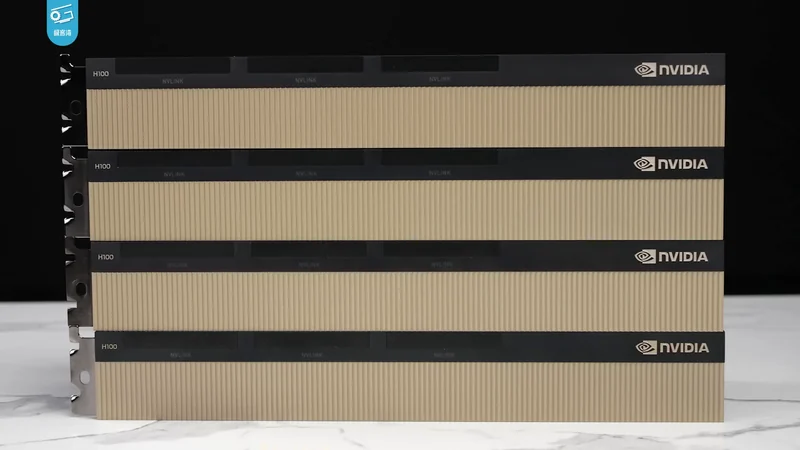
At 24 frames per second, the system needs to produce four frames roughly every 167 milliseconds. Runway reduced repeated work on the cache that holds information from earlier chunks. In its tests, the optimizations cut the diffusion step from 240.9 to 159.3 milliseconds and sustained 24.5 fps on four H100 GPUs. A subsequent optimization that combines computation and communication across GPUs brought that step down to 147.4 milliseconds. [1]
How long a full turn takes
Frame decoding runs in parallel on a dedicated GPU. Diffusion time measures one stage of the pipeline. The preprint reports a median of 2.1 seconds for the full conversational turn. [2]
What to check in practice
To assess a conversation, time the interval between finishing your sentence and seeing and hearing the reply. Repeat with short and long turns. Frame rate helps describe how smooth the video looks, while that interval measures the wait a participant experiences. The cited engineering post sets no new availability by country.